Self-Supervised LearningTraining without human labels
Self-supervised learning is a machine learning method where a model creates its own training signals directly from raw data instead of relying on human labels. The system takes an input, hides or modifies a piece of it, and tries to predict the missing part. This lets neural networks learn underlying patterns from vast amounts of unlabeled text, audio, or images before tackling a specific job.
By the edgi team We find the most surprising true thing about an idea and build a 60-second lesson around it.
A supervised image classifier needs examples paired with answers: this photograph is a cat, this one is a bicycle, and this one is a toaster. In 2007, Fei-Fei Li’s team began building that kind of collection at enormous scale. They used crowdsourcing, paying people online to sort and label images.
Nearly 50,000 workers from 167 countries contributed over two and a half years. The result was ImageNet, with more than 14 million labeled photographs. ImageNet helped transform computer vision. It also exposed a bottleneck: every new labeled example required more human work.
The data supplies the answer
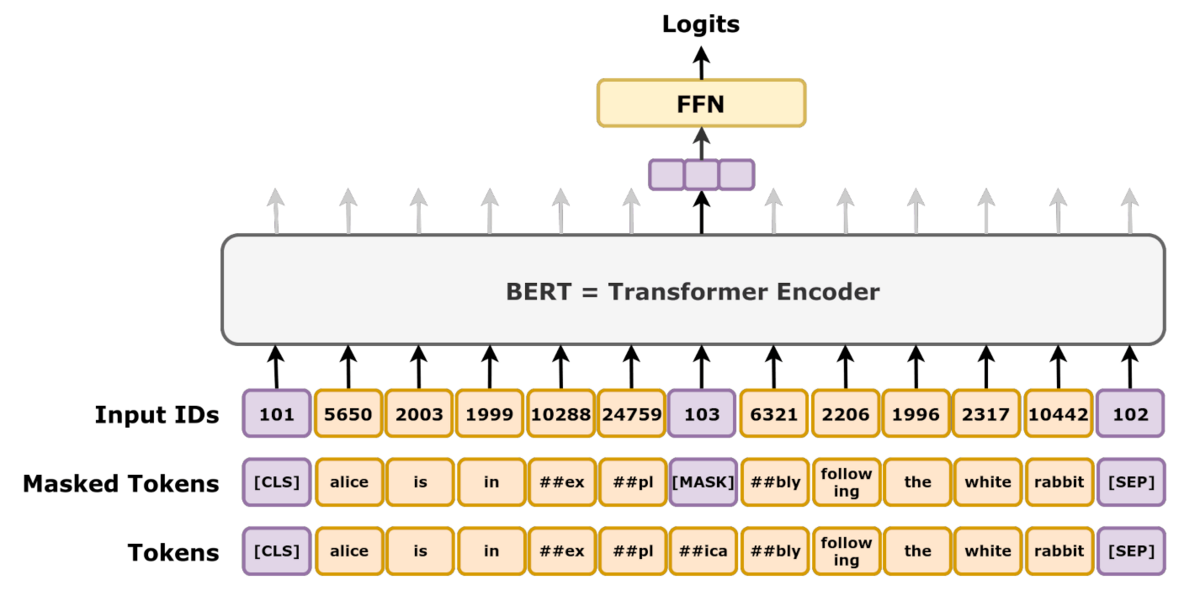
Self-supervised learning turns raw data into a prediction task that uses part of the data as its answer. One method hides part of a sentence and asks the model to predict what is missing. The original sentence provides the correct answer.
Diagram illustrating the BERT masked language modeling task, showing the process of input IDs being fed into a Transformer Encoder. Daniel Voigt Godoy, CC BY 4.0, via Wikimedia Commons
The model can create exercises like this across a vast collection of text without a person labeling every sentence by hand. Training still requires data preparation and enormous amounts of computation. What disappears is the need to attach a human-written answer to every example.
Practice before the real job
Predicting a missing word is usually not the final job. It is a practice task that forces the model to learn how words and ideas tend to relate. An image model can practice in a similar way by rebuilding hidden patches of a photograph from the parts it can still see.
After this initial training, a much smaller labeled dataset can adapt the model to a specific task, such as answering questions or recognizing objects. Self-supervised learning does not eliminate labels from every stage. It lets much more learning happen before those labels are needed.
How self-supervised learning works
Instead of waiting for people to annotate millions of files, a self-supervised model generates its own practice tasks, known as pretext tasks. The system transforms raw input by cropping, adding noise, or rotating it, and then challenges itself to reconstruct the original data or predict the hidden components.
Training happens in two steps. First, the auxiliary pretext task generates pseudo-labels, which are automated predictions the model treats as surrogate answers to set up its internal parameters. Second, the model applies this learned foundation to its actual target task using standard supervised or unsupervised training.
Two main approaches: autoassociative and contrastive
In autoassociative learning, a neural network learns by trying to rebuild its exact input. Autoencoders pass data through an encoder into a lower-dimensional space, then use a decoder to reconstruct the original sample. The system minimizes the mathematical difference between the input and output, storing core structural patterns in its compressed representation.
Contrastive learning takes a different angle by comparing pairs of data. The model learns to pull matching positive examples closer together while pushing unrelated negative examples apart. Contrastive Language-Image Pre-training (CLIP), for instance, jointly trains image and text encoders so matching image-text pairs share closely aligned vectors.
Handling changing data over time
Self-supervised systems can continuously adapt when data patterns shift over time, an issue called concept drift. When new inputs deviate from past examples, the model creates fresh pseudo-labels for high-confidence predictions.
These automated labels allow the network to refresh its outdated components on the fly. Systems deployed in dynamic real-world settings, such as speech recognition pipelines at Facebook, use this method to stay accurate without ongoing manual annotation.
Test yourself
How does self-supervised learning generate its training signals?
By hiding part of the data and predicting it. Self-supervised learning turns raw data into a prediction task by masking a portion of the input, using the unmasked data to predict the missing piece.
What is the primary purpose of pre-training a model with self-supervised learning?
To learn broad patterns before fine-tuning. Pre-training lets a model build a rich understanding of structure using unlabeled data, so it can be adapted efficiently with a smaller labeled dataset later.
How does a self-supervised model train without human labels?
It hides part of the data as the target. The system conceals parts of raw sentences or images and uses the original hidden content as the correct answer for the model to predict.
Play the lesson in edgi and the card is yours. It lands on your Map next to the ideas it connects to, and turns from matte to foil to gold as you learn more around it.
Pseudo-labels are artificial labels that a machine learning model assigns to unlabeled data based on its own confident predictions. The system treats these generated predictions as surrogate truth to keep training on raw inputs.
Where is self-supervised learning used in real applications?
It is widely used in audio processing and speech recognition systems, including speech technology developed by Facebook. It is also used in multimodal systems like CLIP to connect text descriptions with matching images.